When enterprise IT leaders ask whether to invest in AIOps, MLOps, or both, the solution shapes budgets, team structures, and competitive positioning for years to come. These two disciplines share DNA: both leverage AI and machine learning, both promise efficiency gains, and both are growing fast. Yet they solve fundamentally different problems. Conflating them leads to misaligned investments, duplicated tooling, and underperforming strategies.
This guide explains what each discipline does, where they overlap, and how to decide which belongs in your enterprise roadmap.
What is MLOps and Why Does It Matter for Your Enterprise AI Strategy?
MLOps, Machine Learning Operations, is the operational framework that governs how machine learning models are built, deployed, monitored, and maintained at scale. It merges machine learning engineering, DevOps practices, and data engineering into a unified discipline. The goal is to turn experimental ML models into reliable, production grade systems that generate consistent business value.
Without MLOps, most ML projects stall between the proof of concept stage and production. Data scientists build promising models; those models never reach customers at scale because the organizational and technical infrastructure to deploy and sustain them does not exist. MLOps closes that gap.
Get Started with AI and ML Services
A standard MLOps lifecycle includes:
- Business objective definition, aligning model goals with measurable outcomes
- Data collection and processing, ingesting, cleaning, and labeling training data
- Model development, training, tuning, and selecting the best performing algorithm
- Model deployment, packaging and releasing models to production environments
- Monitoring and retraining, detecting model drift and triggering automated retraining
- Governance and versioning, maintaining audit trails, reproducibility, and compliance
For planning, assess your own model portfolio and track measures such as deployment lead time, release failures, recovery time, prediction quality, and cost per prediction. Market projections and adoption surveys should be used only when their publication dates, definitions, and populations are clear.
For a closer look at how MLOps relates to adjacent engineering disciplines, see our comparison of MLOps vs DevOps: Key Differences.
What is AIOps and How is It Transforming IT Operations?
AIOps, Artificial Intelligence for IT Operations, applies AI and ML to automate and enhance how IT operations teams manage complex infrastructure. It ingests high volume operational data, logs, metrics, events, and traces, and uses analytics and automation to surface actionable intelligence in real time.
Where traditional IT operations rely on manual correlation and reactive troubleshooting, AIOps delivers proactive, predictive, and automated responses.
Core capabilities include:
- Anomaly detection across logs and metrics
- Event correlation that reduces alert noise
- Root cause analysis (RCA) that shortens time to diagnosis
- Automated remediation that resolves known issues without human intervention
- Predictive capacity planning that anticipates resource constraints before they impact service
Evaluate AIOps against your operational needs, data readiness, and existing processes. Establish a baseline before using adoption or market figures to support an investment case.
AIOps does not replace skilled IT operations teams. It can help them manage larger, more complex environments with less manual investigation and reactive work.
For example, when a customer service is slow, AIOps can correlate application traces, infrastructure metrics, and recent configuration changes to help teams investigate the incident in context. Any automated response should follow approved permissions and change controls.
What Are the Core Components of AIOps?
AIOps depends on connected data, service context, analytics, and operational workflows.
| Component | Enterprise function | What leaders should validate |
| Telemetry ingestion | Collects logs, metrics, traces, events, and operational records | Data coverage, freshness, access controls, and collection cost |
| Data normalization and enrichment | Aligns timestamps, identifiers, ownership, and configuration context | Consistent service and asset identifiers |
| Service topology | Maps dependencies between infrastructure, applications, and business services | Accuracy of relationships and ownership information |
| Analytics and correlation | Detects anomalies, groups events, and identifies likely causes | Precision and performance on actual incidents |
| Workflow integration | Connects insights to incident, collaboration, and change systems | Clear ownership, evidence, and escalation paths |
| Remediation and governance | Executes approved actions and records outcomes | Permissions, approval gates, auditability, and rollback |
AIOps Vs MLOps: Roles, Layers, and Ecosystem Overlap
Understanding the significant differences between AIOps and MLOps starts with recognizing that both operate within the same broader AI for IT operations ecosystem but at different layers. MLOps also supports business applications outside IT operations, including forecasting, recommendations, and fraud detection.
| Dimension | AIOps | MLOps |
| Primary domain | IT operations | Machine learning engineering |
| Core problem solved | Operational noise, incident resolution, infrastructure reliability | Model deployment, drift, scalability, and lifecycle governance |
| Primary user | IT operations, SRE, and NOC teams | Data scientists, ML engineers, and platform teams |
| Data consumed | Logs, metrics, events, and traces | Training datasets, features, and model outputs |
| AI role | Applies AI to IT operations | Manages AI and ML models as production assets |
| Key outcome | Faster incident response and reliable IT services | Reliable, scalable model deployment and monitoring |
| Governance focus | IT controls, service levels, and operational auditability | Model validation, lineage, and audit trails |
| Time horizon | Real time and near real time | Ongoing model lifecycle management |
The overlap is real but bounded. AIOps platforms may use machine learning models for anomaly detection and root cause analysis. Those models can benefit from MLOps practices for development, deployment, and maintenance.
That does not mean every AIOps buyer needs to operate a separate MLOps platform. The need depends on whether the organization builds, customizes, or manages the underlying models.
Useful link: How Digital Transformation in Finance and Accounting is Reshaping Business Operations?
MLOps Vs AIOps Use Cases Across Enterprises
Real world application is the clearest differentiator. Exploring common AIOps use cases shows where each discipline delivers the greatest business AI operations value and what it is designed to accomplish.
A) MLOps Use Cases in Enterprise AI Systems
1) Predictive Analytics and Demand Forecasting
Retailers, manufacturers, and financial institutions use MLOps pipelines to deploy and continuously retrain forecasting models. MLOps services ensure those models remain accurate as market conditions shift, without requiring manual intervention.
2) Recommendation Engines
Streaming platforms and e-commerce companies rely on MLOps to run continuous training cycles for recommendation algorithms. MLOps infrastructure automates A/B testing, model promotion, and rollback when performance degrades.
3) Fraud Detection and Risk Management
Financial institutions leverage MLOps to deploy real time fraud detection models that adapt to new attack patterns. The ability to retrain and redeploy models rapidly, without service interruption, is a direct MLOps capability.
4) Healthcare Diagnostics
MLOps enables scalable deployment of diagnostic imaging models and personalization engines in healthcare, while maintaining the audit trails and validation records required for regulatory compliance.
5) Natural Language Processing Applications
From enterprise chatbots to contract analysis tools, MLOps manages the lifecycle of NLP models, monitoring output quality, triggering retraining when accuracy drops, and maintaining version governance.
B) AIOps Use Cases in IT Operations and Infrastructure
1) Anomaly Detection and Incident Management
AIOps platforms analyze logs and telemetry to identify anomalies and group related events. Measure alert quality and noise reduction in your own environment, including false positives and missed incidents.
2) Root Cause Analysis and MTTR Reduction
By correlating events across distributed systems, AIOps can help teams investigate incidents more efficiently. Actual time savings depend on telemetry coverage, service topology, and incident type.
3) Hybrid and Multi Cloud Observability
AIOps tools unify visibility across on premise, cloud, and edge environments, a critical capability for enterprises managing complex hybrid infrastructures.
4) Capacity Planning and Resource Optimization
Organizations use AIOps to predict resource utilization trends and right size infrastructure, directly reducing cloud spend.
5) Automated Remediation and Self Healing Systems
Mature AIOps implementations trigger automated remediation workflows for known failure patterns, resolving issues without paging an engineer at 2 a.m.
Benefits of MLOps for Enterprise AI Scalability and Governance
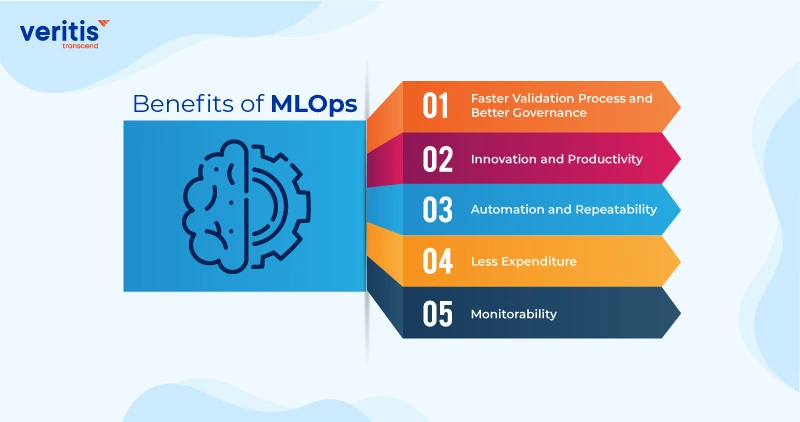
1) Faster Validation and Stronger Governance
MLOps enforces structured validation at every pipeline stage: data, model, and code. It produces audit trails, version histories, and automated reporting that satisfy both internal governance requirements and external compliance mandates. For regulated industries, this is not optional. It is the foundation of trustworthy AI.
Capabilities include:
- Conducting compliance audits with documented model lineage
- Explaining business decisions made by automated systems
- Enforcing bias mitigation policies
- Validating data processing steps before training begins
2) Accelerated Innovation and Team Productivity
MLOps self service ecosystems give data scientists, ML engineers, and analysts access to curated, validated data environments. Engineers spend less time cleaning corrupt datasets and more time building models.
Measure deployment lead time against your own baseline rather than assuming a standard improvement.
3) Automation and Repeatability at Scale
Every pipeline component, data ingestion, feature engineering, model training, validation, deployment, and rollback, can be fully automated. Automation creates repeatability: the same high quality process executes consistently, regardless of team size or model complexity. This is foundational to scaling AI automation tools across an enterprise.
4) Reduced Operational Expenditure
Automated model management reduces the headcount required to maintain a growing portfolio of ML models. Teams do not need dedicated engineers to monitor each model manually.
Drift alerts should prompt investigation. Retraining and production promotion should occur only after defined evaluation and approval criteria are met.
5) Continuous Monitoring and Drift Detection
MLOps solutions maintain production model quality through:
- Continuous retraining triggered by data drift or performance degradation
- Threshold based alerts when model accuracy falls below acceptable levels
- Performance dashboards that surface latency, prediction quality, and data distribution shifts
For organizations exploring where AI fits into their broader transformation agenda, our analysis of 4 Key Areas to Apply Data and Analytics in Digital Transformation provides strategic context.
MLOps Best Practices That Maximize Business Impact
1) Data Validation
ML pipelines can encounter distribution shifts, schema changes, and label problems. Validate statistical properties and formats, and check data for leakage before training.
2) Model Validation
Model testing cannot rely on simple pass/fail thresholds. Use statistical validation approaches that evaluate multiple performance metrics simultaneously. Track experiments systematically and enforce thorough validation gates before promoting any model to production.
3) Code Quality Checks
Use linting, unit tests, and integration tests to catch errors in training pipelines and application code before release.
Also test feature transformations and verify that training and production use compatible data definitions.
4) Continuous Monitoring
Production ML systems depend on factors outside engineering control, particularly data quality in live environments. Monitor four key dimensions:
- Latency, model inference response times
- Traffic and scalability, requests per second and throughput
- Error rates, prediction failures and system errors
- Saturation, resource utilization approaching capacity limits
Add model specific monitoring: prediction distribution shifts, changes in feature importance, and correlations with business metrics.
5) Experimentation Infrastructure
MLOps creates the infrastructure for systematic experimentation. Experiment tracking tools log hyperparameters, training runs, and evaluation metrics, making results reproducible and comparable. Structured experimentation accelerates the identification of performance improvements without losing institutional knowledge between runs.
Schedule an AI and ML Consultation
AIOps Benefits That Help Optimize IT and Reduce Costs
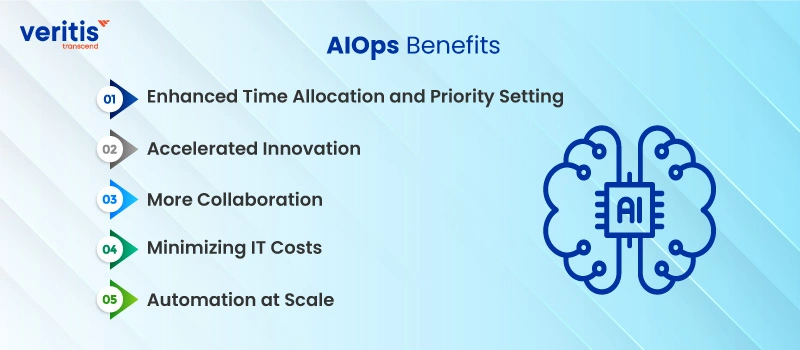
1) Enhanced Time Allocation and Intelligent Prioritization
AIOps platforms process volumes of operational data that no human team can handle manually. They separate signal from noise, enrich events with contextual metadata, and prioritize incidents by business impact. IT teams focus on what matters most. ML powered event correlation accelerates root cause identification and reduces resolution time.
2) Accelerated Innovation Through Operational Freedom
When AIOps handles routine operational tasks, monitoring, alerting, and first line remediation, IT teams reclaim capacity for strategic work. Innovation accelerates when skilled engineers are not consumed by alert fatigue and reactive incident management.
3) Cross Team Collaboration and Unified Visibility
AIOps breaks down operational silos by presenting a unified, data driven view of infrastructure health across teams and departments. When development, operations, and security teams share the same operational intelligence, collaboration improves, and handoff friction decreases.
4) Measurable IT Cost Reduction
AIOps delivers cost savings through multiple mechanisms:
- Proactive issue prevention reduces costly unplanned outages
- Automated remediation replaces manual triage for known failure patterns
- Right sized infrastructure driven by AI powered capacity planning reduces cloud waste
- Reduced MTTR limits the business impact duration of incidents that do occur
Assess realized savings against platform, telemetry, integration, training, and ongoing administration costs.
5) Automation at Enterprise Scale
AIOps enables organizations to build secure automation across their entire infrastructure, spanning all services, environments, and teams. Scalable automation, combined with self service capabilities, ensures that both centralized IT and distributed business units benefit equally from operational improvements.
Market growth alone does not establish enterprise ROI. Build the business case around operational baselines and the total cost of implementation.
AIOps Best Practices for Efficient Implementation and ROI
1) Identify Applicable Data and Data Sources
Before deploying any AIOps platform, map every data source that feeds IT operations: logs, metrics, events, traces, CMDB records, and ticketing systems. Understand the format, location, and quality of each source. Fragmented or inconsistent data requires standardization before it can drive reliable AI inference.
2) Maintain High Data Quality Standards
AIOps is only as reliable as the data it consumes. Establish and enforce data quality standards covering completeness, accuracy, timeliness, and consistency. Invest in data governance tooling that continuously monitors data quality and flags degradation before it affects the effectiveness of your AIOps strategy.
3) Define an AI Utilization Policy
Every team using AIOps outputs must understand how the platform makes decisions, where human judgment is still required, and how data security is maintained throughout the automation workflow. Document roles, responsibilities, escalation paths, and override procedures. A clear AI utilization policy prevents both overreliance and underutilization.
4) Run a Contained Pilot Before Full Rollout
Validate your AIOps solutions approach with a bounded pilot project, a single service, team, or environment, before scaling organization wide. Measure infrastructure performance, team adoption, and incident metrics during the pilot. Use results to refine tooling, training, and integration architecture before broader deployment.
5) Monitor Continuously and Audit Periodically
Ongoing network performance monitoring is non negotiable when AIOps is live. Use monitoring tools with AI and ML analytics capabilities to track performance in real time. Supplement continuous monitoring with periodic independent audits, either internal or third party, to evaluate each component’s contribution to overall operational performance.
For organizations thinking through the governance and security dimensions of AI powered operations, our overview of Key Differences Between Deep Learning and Machine Learning provides foundational context on the underlying technologies.
How Do Monitoring and Feedback Loops Differ?
AIOps monitors IT service health and operational responses. MLOps monitors both model serving reliability and prediction quality. A prediction endpoint may be available while its output quality declines, so infrastructure monitoring alone is not sufficient for MLOps.
Retain (Revisit)Keep workloads on premises for nowCompliance constraints or recent capital investment
| Feedback element | AIOps | MLOps |
| Primary question | Is the service healthy, and did the response work? | Is the model serving reliably and making useful predictions? |
| Main evidence | Telemetry, incidents, change records, recovery outcomes | Features, predictions, labels, evaluation results, business outcomes |
| Typical action | Adjust alerting, escalate, or run an approved workflow | Investigate data, retrain, validate, promote, or roll back |
| Human control | Incident ownership and remediation approval | Model ownership and release approval |
| Success condition | Restored service and acceptable operational risk | Acceptable model quality, service performance, and governance |
Useful link: How Digital Transformation in Finance and Accounting is Reshaping Business Operations?
AIOps vs MLOps: Key Comparison for Business Leaders
The most important thing enterprise leaders need to understand about AIOps vs MLOps is that they are complementary, not competitive. The decision is rarely either/or.
| Criterion | AIOps | MLOps |
| What it manages | IT operations processes and infrastructure | Machine learning model lifecycle |
| Primary objective | Operational reliability and cost efficiency | Scalable, governed AI/ML deployment |
| Powered by | AI/ML applied to operational telemetry | DevOps principles applied to ML workflows |
| Typical buyers | CIO, VP of IT Operations, SRE leads | CTO, Chief Data Officer, ML Engineering leads |
| ROI drivers | Reduced MTTR, lower incident costs, fewer outages | Faster model deployment, reduced data science overhead |
| Implementation timeline | 3 to 9 months for initial capability | 6 to 18 months for mature pipelines |
| Key risk without it | Alert fatigue, slow incident resolution, rising IT costs | Model degradation, shadow AI, compliance exposure |
| Best deployed when | IT environments are complex, hybrid, or multi cloud | Multiple ML models are in or approaching production |
Implementation timelines vary by scope, data readiness, integration requirements, governance, and internal capacity.
Decision framework for executives:
- If your primary pain is IT operational complexity, alert noise, slow incident resolution, rising infrastructure costs, prioritize AIOps.
- If your primary pain is getting ML models to production reliably and governing them at scale, prioritize MLOps.
- If you are running both a complex IT estate and a growing AI/ML program, invest in both, sequenced by the higher priority pain point.
Organizations scaling digital transformation programs may need both disciplines operating in concert. AIOps supports infrastructure reliability; MLOps supports reliable and governed machine learning systems.
How Should Leaders Measure ROI?
Choose a bounded business problem and document its baseline before purchasing or expanding a platform. For AIOps, this could be recurring incidents affecting a critical service. For MLOps, it could be a model release process that is slow, manual, or difficult to audit.
Evaluate results against total operating costs. Track incident impact, engineering time, model delivery, service reliability, and business outcomes where attribution is credible. Scale after a pilot demonstrates both value and control..
Top AIOps vs MLOps Tools Used by Enterprises
Choosing the right AIOps and MLOps tools enables enterprises to automate, deploy, monitor, and govern machine learning models at scale.
Tool capabilities, packaging, and licensing can change. Treat the following as examples to evaluate, not a ranked list. Confirm current product details directly with vendors.
Examples of AIOps Platforms
1) Dynatrace: Observability, anomaly detection, and root cause analysis.
2) Moogsoft: Event correlation and incident management capabilities.
3) Splunk IT Service Intelligence (ITSI): Monitoring and analytics for enterprise IT environments.
4) New Relic: Observability and performance monitoring.
5) PagerDuty AIOps: Incident response and workflow automation.
Examples of MLOps Platforms
1) MLflow: Experiment tracking, model packaging, and registry capabilities. MLflow AI Platform
2) Kubeflow: Kubernetes native machine learning workflows.
3) Amazon SageMaker: Managed machine learning development and deployment services.
4) Azure Machine Learning: Machine learning lifecycle and governance capabilities.
5) Databricks MLflow: MLflow capabilities integrated with Databricks workflows.
Tool selection should align with your existing cloud and data infrastructure. Enterprises should compare integration effort, model governance, data handling, operating requirements, and total cost.
Conclusion
The AIOps vs MLOps question ultimately comes down to where your enterprise’s most significant operational risk lies. AIOps addresses the risk of IT complexity overwhelming your operations team and eroding AIOps services’ reliability. MLOps addresses the risk of AI initiatives stalling before they deliver business value, or degrading after deployment without anyone noticing.
Both disciplines are growing rapidly, both are well past the hype stage, and both are increasingly table stakes for enterprises serious about AI driven operations. The organizations pulling ahead are not choosing between them. They are sequencing investment thoughtfully, building the governance and tooling infrastructure for both, and treating operational AI as a strategic capability rather than a technology experiment.
Veritis works with enterprise IT and data leadership teams to assess operational maturity, design implementation roadmaps, and execute AIOps and MLOps programs that deliver measurable outcomes, not just platforms. If your organization is ready to move from evaluation to execution, the conversation starts here.
Request a Customized AIOps and MLOps Assessment