MLOps, or Machine Learning Operations, combines people, processes, and automation to deploy, monitor, govern, and improve machine learning models throughout their lifecycle.
Until recently, we were all focused on understanding the software development lifecycle (SDLC) and its phases, which typically include requirements elicitation, design, development, testing, deployment, and maintenance. During this period, our focus was on studying different approaches, including the Waterfall, iterative, and Agile software development models.
Presently, nearly every organization is actively working to integrate AI/ML capabilities into its products. This emerging need to develop ML systems introduces or modifies certain aspects of the traditional SDLC, leading to a distinct engineering field known as MLOps. This transformative approach has led to new roles, services, and innovations, such as MLOps solutions, MLOps infrastructure, and MLOps as a service, providing scalable systems that support the entire ML lifecycle.
MLOps and ModelOps are related, but the terms are not exact synonyms. MLOps focuses on operationalizing machine learning systems, while ModelOps can cover a broader range of AI and analytical models. Edge deployments can also add requirements for secure, reliable model operations.
In 2023, most surveyed organizations plan to increase their investments in MLOps substantially. Specifically, 42% of respondents indicated that their organizations plan to increase spending by 11-25%, while 37% plan to increase it by 26-50%. Additionally, 16% aim for a 51-75% increase, 5% expect a 76-100% surge, and just 2% anticipate a modest 10% or less increase. These figures reflect a significant upward trend in MLOps investment.
The global MLOps market was valued at $3.16 billion in 2025 and is projected to reach $65.52 billion by 2034, growing at a 40.07% CAGR from 2026 to 2034, according to The Insight Partners. theinsightpartners.com
Moreover, 98% of respondents intend to increase their investments by at least 11%, and 58% plan to increase their expenditure by over 25%. These statistics underscore a strong commitment to MLOps solutions and a deep belief in their potential to drive business growth.
Notably, these numbers significantly surpass Gartner’s projection of a 5.1% growth in overall IT related spending for the year. This divergence underscores the growing importance and value organizations place on MLOps infrastructure and its promising future.
MLOps is gradually becoming a self sustaining methodology for the entire machine learning lifecycle, covering every stage from data collection through governance and ongoing monitoring. As artificial intelligence becomes increasingly integrated into daily business operations, it is transitioning from being a purely innovative endeavor to a standard practice.
What is MLOps?
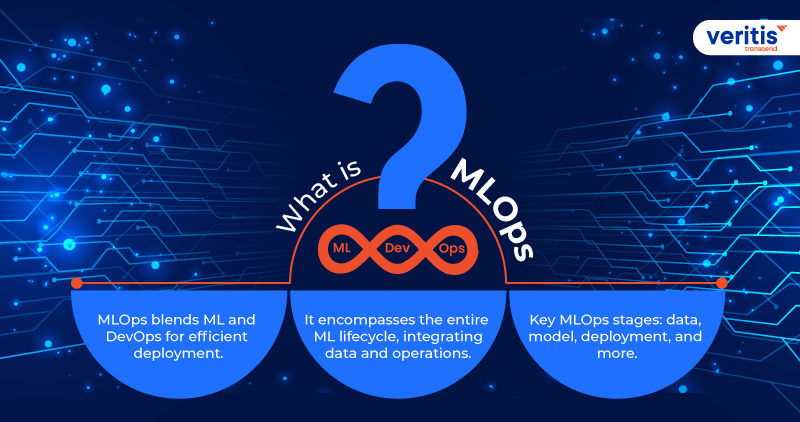
MLOps, a portmanteau of “machine learning” (ML) and “operations” (Ops), encompasses a range of management techniques tailored for the lifecycle of deep learning and production ML. It integrates ML and DevOps practices with data engineering procedures, all geared toward the efficient, reliable deployment of ML models in production environments and their subsequent maintenance. The core objective of MLOps is to enable effective management of the machine learning model lifecycle by fostering communication and collaboration between operations experts and data scientists. This is particularly crucial when understanding the difference between machine learning and deep learning, as both play unique roles within mlops frameworks.
MLOps, with its primary focus on the operational aspects of ML models, falls within the broader ModelOps domain. ModelOps, in turn, encompasses the operationalization of AI models across various domains, including ML models.
MLOps improves the quality and reliability of production machine learning through automation, monitoring, and governance. It brings together practices from data engineering and DevOps while addressing the specific needs of machine learning systems.
Although both DataOps and DevOps are advanced frameworks of best practices, MLOps has evolved differently. MLOps has broadened its scope to encompass the entire ML lifecycle, including integration with model generation, continuous integration and delivery (CI/CD), deployment, orchestration, governance, health monitoring, diagnostic analysis, business metrics assessment, and the traditional software development lifecycle.
This has led to a self sustaining approach to managing the ML lifecycle and fostering an ML engineering culture that applies DevOps best practices to the ML landscape, effectively merging development and operations into what we now call MLOps. The continuous drive for monitoring and automation across all ML system development stages, including testing, integration, deployment, release, and mlops infrastructure management, remains a core tenet of practicing MLOps for machine learning operations.
The essential stages of MLOps encompass:
- Data collection
- Data scrutiny
- Data preprocessing
- Model design and training
- Model verification
- Model deployment
- Model surveillance
- Model refinement and retraining.
Useful Link: AIOps Use Cases: How Artificial Intelligence is Reshaping IT Management
MLOps also requires versioning and tracking the data, code, configuration, and model artifacts used in each release. This helps teams reproduce results, investigate issues, and understand how a production model was created.
What is the Use of MLOps?
MLOps proves invaluable in developing and enhancing machine learning and AI solutions. This approach facilitates productive collaboration between data scientists and machine learning engineers, accelerating model development and deployment through continuous integration and deployment (CI/CD) practices. It also ensures that ML models are appropriately monitored, validated, and governed.
MLOps extends DevOps practices to machine learning. In addition to testing software code, teams need to validate data, evaluate model performance, track model versions, and monitor how predictions perform after deployment.
Why MLOps?
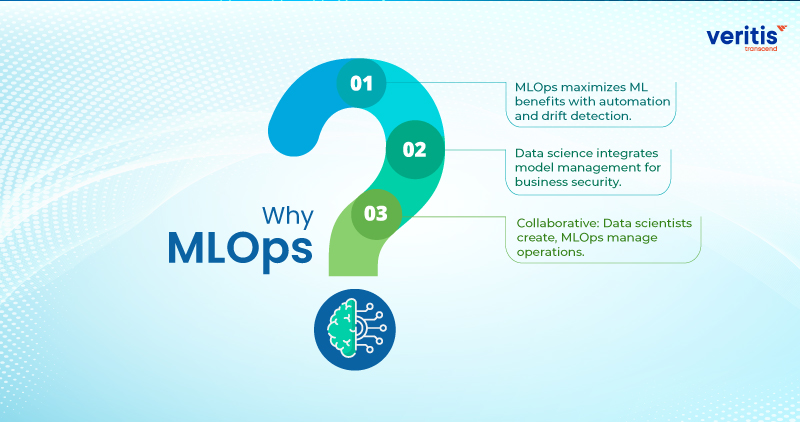
Effectively managing models in a production environment can be challenging. To maximize the benefits of machine learning, these models must enhance efficiency in business applications and contribute to informed decision making as they operate in production. MLOps practices and technologies are pivotal in enabling businesses to deploy, monitor, and govern their ML operations. MLOps specialists support organizations in optimizing model performance and expediting the automation of machine learning processes.
Significant shifts are occurring in data science practices, with a growing emphasis on integrating model management and operational functions to protect businesses from the adverse consequences of inaccurate model outputs. Retraining models with updated datasets is becoming increasingly automated, and timely identification of model drift and issuing alerts when it becomes substantial is paramount.
Furthermore, maintaining the underlying technology of MLOps platforms and recognizing when model upgrades are necessary are integral to optimizing model performance.
This transformation doesn’t imply a shift in data scientists’ responsibilities. Instead, it signifies that machine learning operations practices are breaking down data silos and fostering a broader team approach.
Consequently, this empowers data scientists to concentrate on creating and deploying models, allowing them to prioritize these tasks over making business decisions. Simultaneously, MLOps engineers manage ML models that are already operational.
Why Do We Need MLOps?
Bringing machine learning into production is challenging. The machine learning lifecycle involves numerous intricate stages, including data ingestion, data preparation, model training, fine tuning, deployment, monitoring, explainability, and more. Additionally, it requires close collaboration and seamless handoffs across teams, from Data Engineering to Data Science to ML Engineering.
Maintaining operational excellence is crucial to ensure these processes run smoothly and harmoniously. MLOps encompasses the entire journey of experimentation, iteration, and continuous improvement across the machine learning lifecycle.
A model can remain available as a service while its predictions become less useful. Monitoring should therefore cover service health, data quality, model performance, and business outcomes. Changes in data should prompt investigation; they do not automatically mean a model needs retraining.
Useful Link: Derive ‘ROI’ from ‘DevOps’: An Overview of Performance and Metrics
How to Implement MLOps
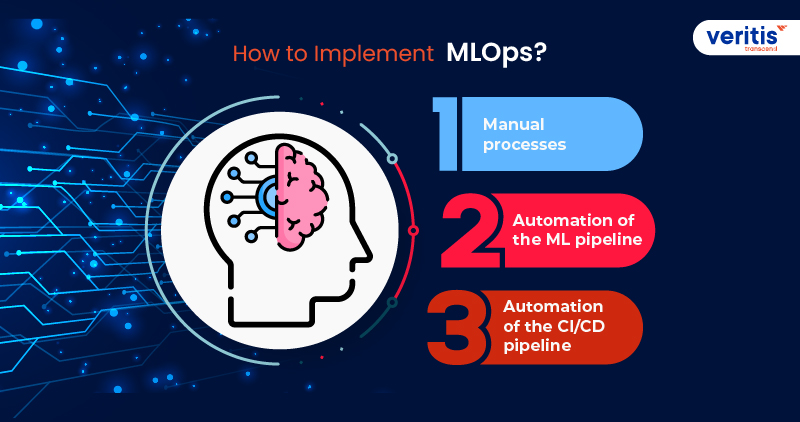
Google suggests three approaches for implementing MLOps:
- MLOps Level 0: Manual processes.
- MLOps Level 1: Automation of the ML pipeline.
- MLOps Level 2: Automation of the CI/CD pipeline.
Google Cloud describes these levels as maturity patterns. They are not certifications, and organizations can adopt the level of automation that fits their models, risks, and release needs.
1) MLOps Level 0
This scenario is common for organizations in the initial stages of adopting machine learning. When your models undergo infrequent changes or training, an utterly manual workflow and a process driven primarily by data scientists can suffice.
At this level, data scientists typically prepare data, train and validate models, and hand off a model for deployment. Releases are infrequent, and teams rely on manual testing and deployment. This can work for early experimentation, but it makes repeatability, monitoring, and collaboration harder as the number of models grows.
Features
1) A Manual, Script Dependent, and Interactive Procedure: Each phase involves manual efforts and encompasses data analysis, preprocessing, model training, and validation. It necessitates hands on execution of every step and manual progression from one phase to the next.
2) Disconnection Between ML and Operational Aspects: The workflow segregates the data scientists responsible for model creation from the engineers in charge of implementing the model as a prediction service. Data scientists provide the engineered team with a trained model as a deployable component for their API infrastructure.
3) Sparse Release Iterations: The premise is that your data science team oversees a small number of models that undergo infrequent changes, either in model implementation or retraining with fresh data. A new model version is rolled out only a few times annually.
4) Absence of Continuous Integration (CI): Continuous integration is overlooked due to the assumption of minimal implementation changes. Typically, code testing is integrated into the notebooks or script execution process.
5) Lack of Continuous Deployment (CD): Continuous Deployment is not considered since frequent model version deployments are scarce. Deployment pertains to the prediction service, a microservice featuring a REST API.
6) Lack of Continuous Performance Monitoring: The process does not oversee or document model predictions and actions. The engineering team could maintain an intricate system for configuring, testing, and deploying the API, including security, regression, load, and canary testing.
Challenges
In practical situations, deployed models frequently encounter issues when operating in real world scenarios. These models struggle to adjust to shifts in environmental dynamics or alterations in the data characterizing the environment. Forbes features an insightful article on this topic, exploring the reasons behind the crash and burn of machine learning models in production.
Manual workflows can make it difficult to detect data quality problems or changes in model performance. Teams can address this by introducing repeatable training pipelines, automated tests, and clear release criteria.
Useful Link: Revolutionizing Software Development: The Power of MLOps
2) MLOps Level 1
The primary objective of MLOps level 1 is to automate the ML pipeline and enable ongoing model training (CT), ensuring a consistent delivery of the model prediction service.
This situation can be advantageous for solutions operating in dynamic environments, where the need to respond proactively to changes in customer behavior, pricing structures, and other indicators is essential.
The pipeline can automate data validation, model training, evaluation, and delivery. Teams can trigger retraining on a schedule, when new data becomes available, or when agreed performance conditions are met. Retraining does not have to happen on every live data event.
Features
1) Swift Experimentation: ML experiment stages are coordinated and executed automatically.
2) Continuous Model in Production: Continuous model training in a production environment involves automatic model training, leveraging real time data triggered by live pipeline events.
3) Symmetry Between Experimentation and Operation: The pipeline implementation utilized in the development or experimental environment is also employed in the preproduction and production environments, serving as a fundamental component of MLOps practices that align with DevOps principles.
4) Modularized Coding for Components and Pipelines: It is essential for building ML pipelines. These components should be designed to be reusable, combined, and potentially shareable across different ML pipelines, often achieved by employing containers.
5) Continuous Model Delivery: Automation is applied to deploying the model, enabling it to serve as a prediction service for online predictions once it’s trained and validated.
6) Pipeline Deployment: In MLOps level 0, you deploy a trained model as a prediction service in the production environment. At level 1, the deployment involves the entire training pipeline, which operates automatically and periodically to deliver the trained model as the prediction service.
Useful Link: Demystifying MLOps vs DevOps: Understanding the Key Differences
3) MLOps Level 2
Implementing a robust automated CI/CD system is imperative to ensure swift and dependable updates of production pipelines. With this automatic CI/CD system, your data scientists can efficiently experiment with new ideas related to feature engineering, model architecture, and hyperparameters.
At this level, teams automate testing and delivery of pipeline changes as well as model releases. It can support organizations with frequent model updates, but the right level of automation depends on business needs, operational risk, and the cost of maintaining the system.
This MLOps setup comprises the following key components:
- Source control
- Testing and building services
- Deployment services
- Model registry
- Feature store
- ML metadata repository
- ML pipeline orchestrator
Useful Link: Successful Digital Transformation: CEO’s Path to Digital Transformation Success
Features
1) Development and Experimentation: Development and experimentation involve an iterative process of experimenting with new ML algorithms and modeling approaches, with orchestrated experiment steps. The output of this stage is the source code for the individual steps of the ML pipeline, which is subsequently uploaded to a source repository.
2) Pipeline Continuous Integration: Pipeline continuous integration encompasses building source code and executing various tests. The results of this phase include pipeline components such as packages, executables, and artifacts, which are slated for deployment in subsequent stages.
3) Pipeline Continuous Delivery: In the continuous delivery phase, the artifacts generated in the CI stage are deployed to the intended environment. This stage results in deploying a pipeline that implements the new model.
4) Automated Triggering: Automated activation involves the automatic execution of the pipeline in a production environment, either following a predefined schedule or in response to a trigger. This stage generates a newly trained model, which is then published to the model registry.
5) Model Continuous Delivery: In the continuous delivery of models, the trained model is made accessible as a prediction service for generating predictions. The outcome of this stage is the deployment of a model prediction service.
6) Monitoring: Monitoring involves gathering performance statistics for the model using real time data.
A model registry and metadata repository help teams track model versions, evaluation results, approvals, and deployment history. Feature stores can help standardize features across training and serving, though they are not necessary for every MLOps implementation.
Practical Steps for Implementing MLOps
A maturity level describes automation. A practical implementation also needs measurable goals, clear ownership, and safe release and recovery processes.
1) Define the business outcome. Select a use case with a business owner and establish baseline measures for model quality, release time, service reliability, and operating cost.
2) Assign responsibilities. Clarify ownership across data science, data engineering, ML engineering, IT operations, security, governance, and the business team. Define who approves releases and responds to production alerts.
3) Build a repeatable pipeline. Track code, data references, configuration, dependencies, model artifacts, and evaluation results for each run. Test data quality and model performance before release.
4) Set release and rollback criteria. Use approval gates and controlled deployment methods where appropriate. Keep a tested rollback path and a fallback process for cases where model predictions are unavailable or unsuitable.
5) Monitor and improve. Monitor service health, data quality, model performance, and business outcomes. Investigate the cause of performance changes before retraining or changing infrastructure.
Choose tools based on required capabilities, existing systems, security needs, integration effort, and total operating cost. See MLOps Tools for Enterprises and learn about Veritis MLOps services.
Case Study: Revolutionizing Healthcare with MLOps Frameworks
A prominent healthcare provider with a strong focus on patient care collaborated with Veritis, to integrate MLOps frameworks. These frameworks were designed to optimize the deployment, monitoring, and management of machine learning models, enhancing both patient outcomes and operational efficiency.
Challenge: The healthcare institution struggled to maintain consistency and scalability across its machine learning (ML) models, particularly in real time applications such as predictive diagnostics and patient monitoring. In these applications, where every second counts, timely insights are not just crucial; they’re life saving.
Solution: Veritis deployed a robust MLOps framework that automated model deployment, enhanced collaboration between data scientists and operations teams, and ensured continuous monitoring of models’ performance in clinical settings.
Results:
- Faster and more reliable model deployment to improve clinical outcomes
- Increased scalability of ML models across multiple healthcare applications
- Continuous model monitoring and performance tuning, ensuring better healthcare insights
The case study reports these qualitative outcomes but does not provide numerical results. Avoid attributing specific clinical improvements without supporting data.
Read the full success story: Breaking Barriers in Healthcare With Intelligent MLOps Frameworks
Conclusion
MLOps helps organizations make machine learning more repeatable, observable, and manageable in production. Start with a defined business use case, establish ownership and release controls, then automate the steps that improve reliability and measurable outcomes.
Furthermore, Veritis offers MLOps services to complement your journey. Backed by 20+ years of experience and a team of AWS, Azure, and GCP certified cloud consultants, we deliver tailored solutions that fit your infrastructure, goals, and budget.