What is MLOps? Machine learning has become a primary driver of competitive advantage, yet deploying models at scale remains one of the biggest challenges for enterprises. Many projects stall after proof of concept, not because the algorithms fail, but because the operational foundation is missing. MLOps best practices address this gap by applying the same discipline and reliability to model development and deployment that you expect from any mission critical system.
MLOps combines engineering practices, operational processes, and governance to develop, deploy, monitor, and maintain machine learning systems throughout their lifecycle. It connects data science, data engineering, software delivery, security, and business ownership.
MLOps best practices can help organizations pursue:
- Faster value capture by reducing the time between AI experiments and real business impact.
- Operational resilience by ensuring models adapt to changes in data and market conditions without disruption.
- Regulatory confidence by embedding compliance, auditability, and ethical safeguards from the start.
- Scalable growth by creating repeatable processes that work across teams, regions, and product lines.
Organisations that treat MLOps solutions as part of their core infrastructure will move ahead of those that see it as an add on to data science. Success is not about putting models into production but about keeping them accurate, reliable, and trusted at scale. This is what turns AI from a one off project into a lasting business capability.
Why MLOps Matters
AI models now run core processes, from credit scoring to supply chain forecasting. When they fail, the business feels it instantly. MLOps best practices ensure these models transition from prototype to production quickly, remain accurate as data evolves, and meet compliance requirements without compromising delivery speed.
Organizations that build a strong MLOps pipeline and adopt machine learning best practices deploy faster, scale more easily, and maintain trust with both customers and regulators. In 2025, the ability to operationalize AI, particularly with MLOps for deep learning, is a defining factor that separates market leaders from those struggling to keep up. The difference lies in executing every ML best practice with precision and scale.
Models used in credit scoring, supply chain forecasting, and other business processes can create operational risk when their data, performance, or dependencies change. MLOps provides repeatable processes for moving models into production, monitoring them, and managing updates.
To evaluate results, establish baselines for deployment lead time, failed releases, recovery time, prediction quality, and cost per prediction. Then measure whether pipeline improvements support the intended business outcome.
How Does MLOps Differ from DevOps?
DevOps manages software delivery and operations. MLOps extends related practices to systems whose behavior also depends on training data, features, model parameters, and changing production conditions. A software service may pass code tests while the model it serves becomes less useful.
| Area | DevOps focus | Additional MLOps requirement |
| Versioning | Code, dependencies, configuration | Data references, features, model artifacts, evaluation results |
| Testing | Functional behavior and service reliability | Data quality, leakage, model quality, bias, prediction consistency |
| Delivery | Build and release software | Train, evaluate, register, approve, and release models |
| Monitoring | Availability, errors, latency | Drift, prediction quality, feature freshness, business outcomes |
| Recovery | Restore an application release | Restore a compatible model, feature definition, and serving environment |
MLOps Process
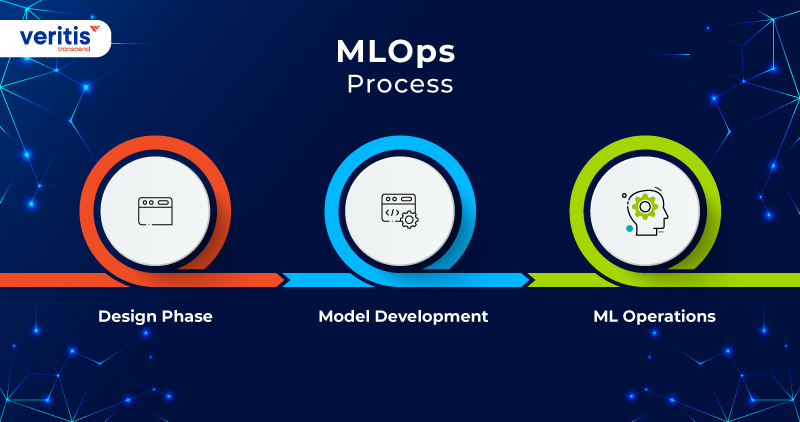
An MLOps process typically includes design, model development, and ML operations. Each stage should have defined inputs, owners, validation criteria, and outputs.
1) Design Phase
This is where intent becomes a plan. Before a single model is trained, the business case is locked in, the data field is mapped, and the success criteria are agreed upon. It is the stage where you decide not what to build but why it matters.
What Happens Here:
- Choose the problem worth solving
- Prioritise use cases that can deliver measurable value
- Verify that the correct data exists and meets quality standards
- Set the performance and compliance bar that the model must clear
2) Model Development
Here, ideas turn into working models. Data engineers prepare clean, relevant datasets. Data scientists test algorithms and features. The best candidates are tuned and tested until they can meet real world demands, not lab benchmarks.
What Happens Here:
- Prepare and structure data for training
- Experiment with multiple algorithms
- Validate performance on unseen datasets
- Record results so they can be replicated and improved
3) ML Operations
The model leaves the lab and joins the business. It is deployed, monitored, and maintained like any other mission critical system. Continuous integration, training, controlled updates as data or business conditions change. Drift is detected early, and retraining is triggered automatically only when defined criteria are met and the candidate model passes evaluation.
What Happens Here:
- Deploy into production environments
- Monitor for accuracy, latency, and unexpected behaviour
- Manage versions for quick rollback if needed
- Automate retraining when data or performance shifts
Useful Link: What is MLOps? Why MLOps and How to Implement It
What Are the Components of MLOps Architecture?
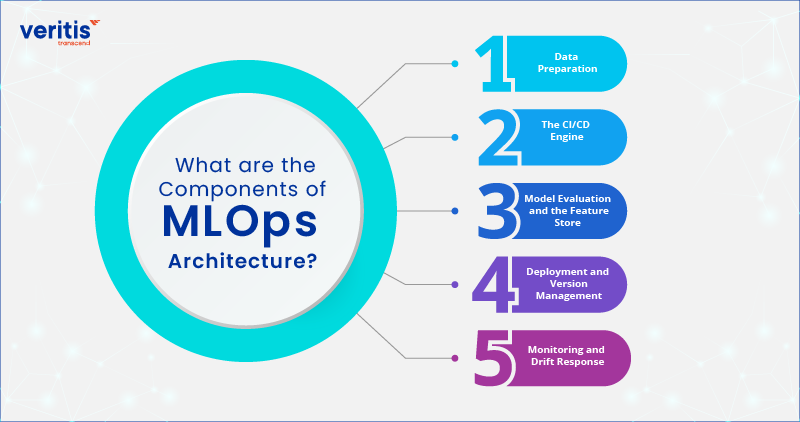
A strong MLOps architecture works like a high performing team. Every role is clear, every handoff is smooth, and nothing falls through the cracks. This is the outcome of applying MLOps best practices across the entire pipeline, aligning every stage from model training to monitoring. Whether you’re scaling traditional models or deploying MLOps for deep learning, success depends on executing each ML best practice with clarity and precision. Here is how the key pieces fit together.
1) Data Preparation
Models are only as good as the data that feeds them. The architecture begins with systems that pull data from multiple sources, automatically check its quality, and shape it into a training ready form. By the time data reaches a model, it has already passed rigorous checks for accuracy and relevance.
What This Delivers:
- Cleaner inputs for better predictions
- Early detection of bad or incomplete data
- Features engineered for maximum predictive power
Exploratory data analysis should check coverage, missing or invalid values, outliers, class imbalance, and differences across relevant segments. Prevent data leakage by excluding information that would not be available when predictions are made. Record assumptions and checks alongside the data version used.
2) The CI/CD Engine
This is the automated pipeline that turns experiments into deployable models. Code, data, and configurations all travel through the same integration and delivery path. Tests and approvals occur along the way, ensuring only production ready assets are approved.
What This Delivers:
- Faster deployment with fewer human bottlenecks
- Consistency between development and production environments
- Built in quality control before release
3) Model Evaluation and the Feature Store
Before a model is cleared for launch, it goes through rigorous evaluation. Features may be maintained in a central repository allowing future models to reuse proven building blocks instead of starting from scratch.
What This Delivers:
- Models that meet performance and compliance thresholds
- Reduced duplication of work
- A shared library of trusted features
A feature store is useful when teams need reusable feature definitions, freshness controls, or consistent access for training and serving. It is not required for every implementation and does not replace model evaluation or a model registry.
4) Deployment and Version Management
Once a model is live, it becomes part of the business workflow. Version management ensures every model in production can be traced back to its source and replaced or rolled back without guesswork.
What This Delivers:
- Confidence in knowing exactly which version is running
- Ability to respond instantly to failures or performance drops
- Clear lineage for auditing and troubleshooting
5) Monitoring and Drift Response
Even the best models degrade over time as data shifts. Automated monitoring tracks accuracy, latency, and data patterns at a frequency appropriate to the use case. If performance dips or drift is detected, retraining can be triggered automatically.
What This Delivers:
- Early warnings before problems affect the business
- A controlled process for evaluating whether updated data warrants retraining.
- Sustained model performance over the long term
When these components work together, MLOps stops being a technical process and becomes an operational advantage. The architecture doesn’t just support models — it supports decisions, revenue, and resilience across the organisation.
Useful Link: Successful Digital Transformation: CEO’s Path to Digital Transformation Success
How Should Teams Manage Model Inference and Serving?
Inference is the use of a trained model to generate predictions. Serving is the infrastructure and application logic that makes those predictions available to business systems. Choose the approach that meets the decision deadline and operating requirements.
| Serving approach | Suitable business need | Primary operating controls |
| Batch inference | Scheduled forecasts, scoring lists, reporting | Completion deadlines, data freshness, reruns, output validation |
| Online inference | Decisions during a customer or operational interaction | Latency, availability, concurrency, timeouts, fallback behavior |
| Streaming inference | Decisions based on continuously arriving events | Event ordering, processing lag, duplicate handling, backpressure |
| Edge inference | Local decisions with limited connectivity or strict latency needs | Device compatibility, resource limits, secure updates, local monitoring |
Validate the full inference path, including preprocessing, feature retrieval, model execution, and response formatting. Use shadow deployments or canary releases when appropriate, and define rollback thresholds in advance. Fallbacks may include a previously approved model, rules based decisions, or a manual workflow.
Which MLOps Framework Fits Your Operating Model?
An MLOps framework may connect orchestration, experiment tracking, artifact storage, model registration, deployment, monitoring, and access control. Choose tools based on required capabilities, existing infrastructure, security, and operational capacity.
MLflow can help teams track experiments, package models, and manage model versions. It still needs to integrate with data versioning, production serving, orchestration, and enterprise security controls.
Kubeflow provides Kubernetes native components for machine learning workflows. It may fit organizations that already operate Kubernetes and need control over compute and pipeline execution. Teams should account for the operational effort of managing clusters, storage, networking, access, and upgrades.
MLflow and Kubeflow can be used together where their metadata, integrations, and access controls are managed consistently. A managed platform or simpler orchestration may be a better fit for teams with less infrastructure capacity.
MLOps in Regulated Industries
In regulated sectors, model governance must address applicable legal and supervisory requirements alongside model accuracy. Finance, healthcare, and government operate under rules that demand transparency, auditability, and control over every model in production. MLOps best practices form the operational backbone that enables this level of governance.
A well structured MLOps pipeline can support compliance processes while maintaining optimal performance. By embedding machine learning best practices and leveraging MLOps for deep learning, organizations can address regulatory demands without sacrificing agility.
MLOps does not itself guarantee compliance. Privacy, security, clinical validation, and legal review remain necessary.
1) Finance
Banks and insurers face strict oversight regarding credit scoring, anti money laundering models, fraud detection, and trading algorithms. MLOps pipelines can log every training run, store every version, and maintain data lineage to help teams trace which model and data were used. Explaining an individual decision may also require suitable explanation methods and decision records.
2) Healthcare
Clinical AI systems, from diagnostic imaging to treatment recommendations, must comply with HIPAA in the US, the GDPR in Europe, and equivalent laws elsewhere. MLOps can enforce approved privacy and deidentification procedures before training, maintain model versions for medical audits, and trigger retraining when new clinical guidelines or updated datasets become available.
3) Government
Public agencies use models for benefits eligibility, tax compliance, and risk assessment. These decisions directly affect citizens, so fairness and explainability are non negotiable. MLOps can include bias checks, release controls, and records of model changes, subject to applicable requirements.
The core value of MLOps in these environments is that compliance is built into the process, rather than being retrofitted after the fact. It helps organizations prepare for review without slowing the pace of delivery.
Apply identity and access management that separates development, approval, and deployment privileges. Restrict sensitive data access, protect secrets, and retain approval evidence according to policy.
From MLOps to ModelOps and LLMOps
The scope of operational AI is expanding. MLOps, once focused purely on machine learning models, is evolving into two broader disciplines.
ModelOps
Where MLOps handles the engineering side of deploying models, ModelOps expands to cover governance, business alignment, and lifecycle management for all analytical models, machine learning, rules based, optimisation, and beyond. It aligns technical deployment with business value tracking, ensuring models remain aligned with the strategy they support.
LLMOps
The rapid adoption of large language models has created new operational requirements. LLMOps applies the same discipline as MLOps, but focuses on managing prompts, fine tuning, context retrieval, and guardrails to reduce the risk of hallucinations or misuse.
Enterprises may operate MLOps, ModelOps, and LLMOps within a shared governance and observability framework. The goal is to manage AI and analytics assets consistently while accounting for their different risks and requirements.
What This Shift Means for C-Suite Leaders?
Enterprises will increasingly run MLOps, ModelOps, and LLMOps in parallel. The winning strategies will integrate these into a single operational framework, with shared governance, observability, and compliance layers. The goal is not to treat these as separate silos, but as parts of a unified model delivery system that covers every AI and analytics asset in the organisation.
Useful Link: How to Implement Artificial Intelligence in DevOps Transformation?
MLOps Best Practices
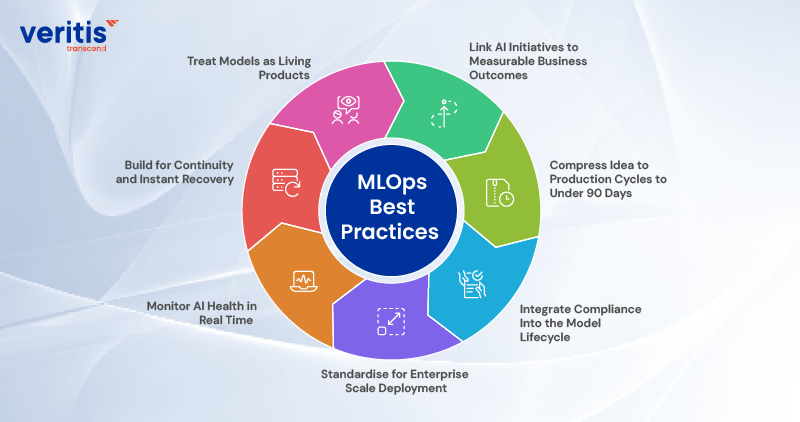
MLOps best practices are crucial for transforming AI prototypes into production ready systems that deliver real business value. A robust MLOps pipeline aligns data science, engineering, and compliance across every stage of the deployment process.
By following proven machine learning best practices, enterprises ensure accuracy, scalability, and trust. Whether scaling across cloud platforms or applying MLOps for deep learning, success hinges on executing every ML best practice with discipline.
1) Link AI Initiatives to Measurable Business Outcomes
Why It Matters: AI must prove its value in terms that the business understands, such as revenue growth, cost savings, risk reduction, or customer retention. Models without clear KPIs are the first to be cut in budget cycles.
ROI Impact: Organisations that align AI projects with business KPIs achieve 3x the ROI of those that do not.
Example: A global insurer directly tied claims processing models to cost per claim reduction targets, achieving a 22% reduction in processing costs in the first year.
Set a baseline, a target, and an accountable business owner before development begins.
2) Set a Risk Appropriate Delivery Target
Why it matters: A deployment delay can erode the first mover advantage. Shorter delivery cycles allow rapid response to market changes and customer needs.
ROI Impact: Fast cycle MLOps can deliver 20–40% greater market capture in high competition sectors.
Example: A retail bank utilized automated CI/CT/CD pipelines to roll out a new credit risk model in 74 days, resulting in an 8% reduction in loan default rates within the first quarter.
Use delivery targets that account for data readiness, validation, compliance, and the risk of the model’s decisions. A 90 day timeline is not a universal requirement.
3) Integrate Compliance Into the Model Lifecycle
Why It Matters: In industries such as healthcare, finance, and government, compliance failures can result in fines, loss of license, or reputational damage. Compliance should be embedded, not retrofitted.
ROI Impact: Proactive compliance reduces audit preparation costs by up to 50% and shortens approval cycles by weeks.
Example: A European healthcare provider embedded bias checks and explainability reports into their MLOps pipeline to comply with the EU AI Act, enabling faster rollout of diagnostic models across three countries.
Define the applicable obligations with legal, compliance, and business stakeholders. Bias checks and explainability reports alone do not establish regulatory compliance.
4) Standardise for Enterprise Scale Deployment
Why It Matters: Without standardisation, every AI deployment is a bespoke project, increasing costs and slowing delivery.
ROI Impact: Shared model registries, feature stores, and governance frameworks can reduce deployment costs by 25 to 30% and halve time to scale.
Example: A multinational telecom operator created a centralised MLOps platform, enabling models built for one market to be deployed in others with minimal changes, cutting replication time from six months to six weeks.
Create reusable pipelines, registries, and governance controls where teams have shared requirements. Validate their cost and operational value before broad adoption.
5) Monitor AI Health in Real Time
Why It Matters: Model drift, latency issues, and rising costs can go unnoticed until they impact customers or revenue.
ROI Impact: Identifying drift early can help large enterprises avoid financial losses that may amount to tens of millions of dollars annually.
Example: An e-commerce leader integrated real time drift detection into its recommendation engines, protecting $50M in projected sales during a seasonal campaign.
Monitor service health, data quality, model performance, and relevant business outcomes. Define who investigates alerts and what evidence is required before a model is changed.
6) Build for Continuity and Tested Recovery
Why It Matters: AI outages can affect critical business processes. Customers expect consistent service, and recovery delays can have operational and reputational consequences.
ROI Impact: Automated rollback and retraining workflows reduce downtime related losses by up to 80%.
Example: A logistics provider used automated failover to switch to backup forecasting models during a data pipeline outage, avoiding service disruptions for 12,000 active shipments.
Maintain a tested fallback, such as a previously approved model or manual process. Retest rollback procedures when models, features, or serving dependencies change. Retraining is not a substitute for an immediately available fallback.
7) Treat Models as Living Products
Why It Matters: Models can degrade as data and market conditions change. Continuous evaluation helps teams determine when a model needs maintenance or replacement.
ROI Impact: Extending a model’s productive life by two to three years can save millions in redevelopment costs.
Example: A fintech firm implemented quarterly model reviews and retraining triggers, keeping its fraud detection accuracy above 96% for three consecutive years.
Review model performance, data quality, business outcomes, and operating cost at an agreed cadence. Retrain or replace a model only when evaluation shows that the change is justified.
How Should Teams Automate and Control the Pipeline?
Automation should make approved processes repeatable without removing accountability. Assign owners for business outcomes, model quality, platform reliability, and material risk decisions.
Automate data checks, feature transformations, training, evaluation, artifact registration, deployment preparation, and monitoring configuration. For each stage, record inputs, outputs, status, and failure reasons. Version code, data references, features, preprocessing, dependencies, model artifacts, and evaluation results so releases can be reproduced.
Continuous training does not mean automatic promotion. Evaluate each candidate model against the production model and agreed quality, risk, and approval criteria before release.
Use tests that address distinct release risks:
| Test layer | Release question |
| Data contracts | Are schema, ranges, freshness, and required fields valid? |
| Transformation tests | Do features behave correctly, including unusual or missing inputs? |
| Model evaluation | Does the candidate meet quality and segment thresholds? |
| Integration tests | Can the application load features and return valid predictions? |
| Load and recovery tests | Can the service handle demand and use its fallback? |
| Security and governance | Are access, artifacts, explanations, and approvals acceptable? |
Monitor service health, data health, model quality, and business impact separately. Data drift means the input distribution changed; concept drift means the relationship between inputs and outcomes changed. Neither automatically means a model should be retrained.
Case Study: Building Scalable MLOps Pipelines for Financial Institutions
A leading financial institution, in collaboration with Veritis as their MLOps partner, embarked on a journey to build scalable MLOps pipelines. This strategic partnership enabled the institution to streamline the deployment of its machine learning model, enhance collaboration, and scale efficiently across multiple teams and platforms.
Challenge: The institution struggled to manage and deploy machine learning models at scale, resulting in delayed decision making, inconsistent model performance, and challenges in maintaining regulatory compliance in the financial sector.
Solution: Veritis implemented end to end MLOps pipelines, utilizing cutting edge machine learning tools to automate the model development, testing, and deployment processes. The solution provided a scalable framework that facilitated continuous model updates, better collaboration among data scientists, and faster time to market for financial services.
Results reported in the case study:
- 60% faster model deployment, from five weeks to two
- 100% model audit readiness
- 40% infrastructure cost reduction
- 15% increase in predictive accuracy
The case study also reports improved cross team collaboration and scalability.
Read the full success story: Building Scalable MLOps Pipelines for Financial Institutions
Conclusion
The accurate measure of artificial intelligence is not in experimentation but in sustained business performance. MLOps provides the structure, governance, and operational discipline required to maintain accuracy, ensure explainability, and enable controlled response to changing conditions without compromising compliance or stability.
Veritis, the esteemed Stevie and Globee Business Awards winner, proudly offers top notch MLOps services to complement your journey. With our expertise, companies can confidently navigate the intricate terrain of MLOps, ensuring that your organization’s machine learning efforts achieve the efficiency and speed required for success. As the demand for MLOps solutions continues to rise, our commitment to delivering top tier services is poised to empower your organization to realize the full potential of your machine learning endeavors.
For organisations seeking to transform AI from a series of initiatives into a long term competitive advantage, Veritis offers the expertise, infrastructure, and operational excellence to make it an enduring part of the business.
Veritis MLOps services help organizations build and manage machine learning pipelines, automate model workflows, and monitor production models. Contact Veritis to discuss your MLOps strategy and implementation needs.